NInfer-4090
Qwen3.8-27B on one RTX 4090
My hobby port of NInfer-3090 to the RTX 4090. It runs a 27B model for a coding agent on one 24 GB consumer GPU.
3,600 tok/s
Prefill on a 9,411-token prompt
One RTX 4090 at 480 W, without cache reuse
148.6 tok/s
Code decode with MTP
Three draft tokens, INT8 KV cache, greedy, one request
262,144
Token context on one 24 GB card
Rotated 4-bit KV cache
101 ms
Six decisions on a cached state
Median, 8,205-token state cached on the GPU, BF16 KV cache
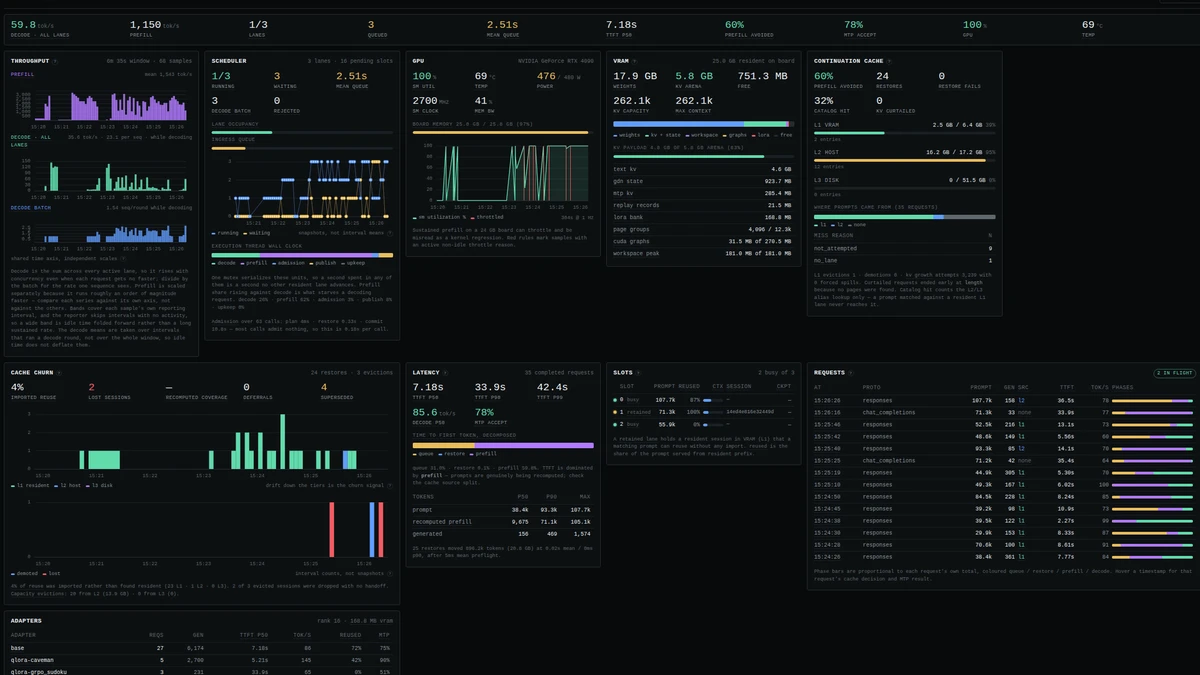
The Problem
I wanted a coding agent to run on a local 27B model, on one 24 GB NVIDIA GeForce RTX 4090. A coding agent resends its whole conversation every turn, so the engine needs fast prefill and a cache that returns the earlier prompt. The NInfer engine by Neroued was developed for the RTX 5090. NInfer-3090 by Don-Chad added an SM86 compatibility layer and Qwen3.8 runtime support for the RTX 3090.
The Solution
I ported NInfer-3090 to sm_89, the RTX 4090, and extended it for agent traffic. Every kernel is tuned for this one model on this one card. The model is a 16.96 GiB artifact with a groupwise Q4/Q5/Q6 body and an 8-bit embedding and output head. A rotated 4-bit KV cache fits the full 262,144-token context on the card. The server speaks OpenAI Chat Completions, OpenAI Responses, and Anthropic Messages with streamed tool calls. It resumes a long agent prompt from the deepest cached point it holds in GPU memory, host RAM, or on disk, and prefills only the new tail. Requests pick a LoRA adapter by name, and requests for different adapters decode in one batch. A decisions API in the same process and on the same weights answers typed questions with probabilities from prefill and a pointer head, without decoding. Caudra uses it as its local decision engine.
Tech Stack
Engine
Model
APIs
Adapters
My Role: Port & Maintainer (Hobby)
- Ported NInfer-3090 to the RTX 4090 (sm_89) and maintain the fork as a hobby project
- Added per-request LoRA adapter serving and the decisions API, which answers both OpenAI /v1/decisions and TypeSafe System One requests
- Added live prefill progress to the Responses stream, which Caudra shows as a prefill-rate bar
- Published the model artifact and the caveman-1 and decision-1 adapters on Hugging Face under Apache-2.0
Want to discuss this experience?
I am open to full-time Senior Data & AI Platform Architect roles. My resume lists the rest of my work.
Other Projects
Caudra
The complete coding agent for your terminal
In public preview for macOS, Linux, and Windows. Free and open source, with first-party work under Apache 2.0 and inherited Maki code under MIT.
Enterprise IoT Platform
Multi-Tenant Workflow Automation Infrastructure
Reduced customer onboarding time by 70% and eliminated an estimated 40+ hours/month of manual DevOps while the architecture was designed for 1,000+ isolated workflow instances.